
Note: This article is a fully rewritten, publication-ready synthesis of real JavaScript SEO practices from search engine documentation, technical SEO resources, and modern web rendering guidance.
JavaScript is the espresso shot of the modern web. It powers slick menus, app-like shopping carts, dashboards, filters, product configurators, interactive maps, and the little button that makes a website feel less like a PDF wearing shoes. But when JavaScript handles your important content, navigation, metadata, or links, SEO becomes more complicated. Not impossible. Not doomed. Just a little more “please test this before launching on Friday at 4:58 p.m.”
JavaScript SEO is the practice of making JavaScript-powered websites crawlable, renderable, indexable, and understandable for search engines. In plain English: can Google, Bing, and other search systems find your pages, read your content, follow your links, interpret your signals, and show the right page in search results? If the answer is “only after three API calls, a user click, and a prayer,” you may have a JavaScript SEO problem.
This guide walks through the major lessons behind JavaScript SEO, including rendering, crawlability, indexation, internal links, metadata, lazy loading, structured data, performance, testing, and real-world troubleshooting. The goal is not to scare you away from JavaScript. The goal is to make JavaScript behave like a helpful teammate instead of a magician who hides your content inside a hat.
What Is JavaScript SEO?
JavaScript SEO is a branch of technical SEO focused on websites where JavaScript affects content, links, metadata, page speed, or user experience. A simple marketing page with a small JavaScript accordion is usually easy to manage. A single-page application built with React, Vue, Angular, or a similar framework requires more planning because the browser may need to execute JavaScript before the full page content appears.
Search engines can process JavaScript better than they could years ago, but “can” does not always mean “will do it perfectly, instantly, and for every page.” Google describes JavaScript processing as a workflow that includes crawling, rendering, and indexing, while Bing also emphasizes crawlability, indexability, and technical accessibility in its webmaster guidance.
The practical question is simple: what does a search engine see before and after JavaScript runs? If the initial HTML contains a blank app shell and the useful content appears only after client-side rendering, your SEO success depends heavily on whether crawlers can render that page correctly and efficiently.
Why JavaScript Can Create SEO Problems
JavaScript is not bad for SEO. That sentence deserves a tiny parade. The trouble begins when important SEO elements are unavailable, delayed, blocked, duplicated, or changed after rendering. Common issues include missing body content, links that are buttons instead of anchor tags, metadata injected too late, canonical tags that conflict, lazy-loaded content that never loads for crawlers, and JavaScript bundles so large they make mobile devices sigh deeply.
A traditional HTML page gives crawlers most of the important information immediately. A heavily client-rendered page may require the crawler to download scripts, execute them, fetch data, build the DOM, and then decide what the page is about. That extra work can slow discovery and increase the chance that something important gets missed.
How Search Engines Process JavaScript
1. Crawling
Crawling starts when a search engine discovers a URL through links, XML sitemaps, redirects, feeds, or submitted URLs. At this stage, crawlers fetch the HTML response. If your server returns a proper 200 status code, allows important resources, and includes discoverable links, you are already being a good host. If your page blocks JavaScript or CSS in robots.txt, returns soft 404 content, or hides everything behind scripts, the crawler has to work harder.
2. Rendering
Rendering is the process of turning HTML, CSS, JavaScript, and fetched data into the final page that users see. Google’s documentation explains that rendered HTML is used for processing JavaScript-generated content, and modern Bingbot uses evergreen rendering technology based on Microsoft Edge.
That is good news, but not a blank check. Rendering consumes resources. Large bundles, slow APIs, blocked files, errors, and timeouts can create gaps between what users see and what crawlers can process.
3. Indexing
Indexing is where the search engine stores and interprets the page. It evaluates text, headings, links, canonical tags, structured data, media, freshness, duplication, and other signals. If the rendered page is different from the server HTML, search engines may rely on the rendered version, but your safest strategy is still to make critical content and signals available as early and reliably as possible.
Rendering Options: CSR, SSR, SSG, and Dynamic Rendering
Client-Side Rendering
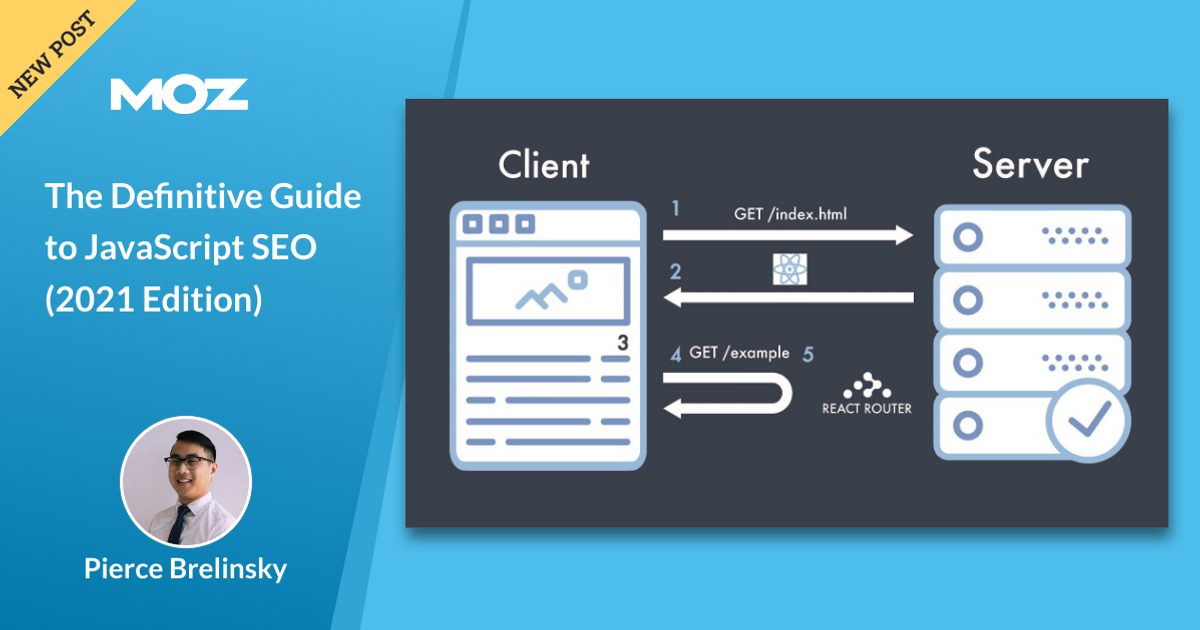
Client-side rendering, or CSR, sends a minimal HTML shell and lets JavaScript build the page in the browser. It can produce a smooth app-like experience, but it also creates SEO risk when the initial HTML lacks meaningful content. CSR can work, especially for logged-in tools or pages where SEO is not important. For public landing pages, product pages, category pages, articles, and local pages, CSR deserves extra testing.
Server-Side Rendering
Server-side rendering, or SSR, generates HTML on the server and sends a more complete page to the browser. This can help users and crawlers see content faster because the server delivers the important markup first. Web.dev and MDN both describe SSR as a model where HTML is generated on the server rather than relying entirely on the client to build the page.
For SEO-critical pages, SSR is often a strong default. It reduces the “please wait while JavaScript assembles the universe” problem and gives crawlers a clearer page from the first response.
Static Site Generation
Static site generation, or SSG, prebuilds pages into static HTML files. It is excellent for blogs, documentation, marketing pages, and many ecommerce category pages where content does not change every second. SSG is fast, stable, and crawler-friendly. The tradeoff is that highly dynamic content may require smart rebuilds, incremental regeneration, or hybrid rendering.
Dynamic Rendering
Dynamic rendering serves a pre-rendered version to crawlers and a JavaScript version to users. Google now describes dynamic rendering as a workaround rather than a recommended long-term solution because it adds complexity and maintenance overhead.
Dynamic rendering can still be useful for certain legacy systems, but modern projects should usually consider SSR, SSG, hydration, or partial rendering instead. In other words, dynamic rendering is a bandage, not a wellness plan.
JavaScript SEO Best Practices
Use Real URLs for Real Pages
Every important page should have a unique, crawlable URL. If users can filter, sort, or navigate to meaningful content, decide whether that state deserves an indexable URL. Product pages, location pages, article pages, and category pages should not exist only as JavaScript states with no stable address.
Avoid hash-based routing for important indexable pages unless you fully understand the implications. Clean URLs are easier for users, analytics platforms, crawlers, and your future self, who would prefer not to debug a routing mystery during lunch.
Make Internal Links Crawlable
Search engines discover pages through links. Use standard anchor tags with href attributes for important navigation. Buttons, divs, click handlers, and JavaScript-only navigation may work for users but fail to pass clear discovery signals to crawlers.
A good internal link looks like this: <a href="/javascript-seo-checklist/">JavaScript SEO Checklist</a>. A risky pattern looks like a clickable element that changes the page with JavaScript but has no crawlable href. It may feel fancy, but search engines are not impressed by mystery doors.
Do Not Block Critical Resources
Search engines need access to the resources required to render the page. That includes JavaScript, CSS, images, and API endpoints when those resources affect visible content. Blocking important scripts or styles in robots.txt can prevent crawlers from understanding the page layout and content.
Run test crawls and inspect rendered HTML to confirm that critical files are accessible. If the crawler cannot load your main JavaScript bundle, it may see a page that resembles an empty apartment: technically a page, but nobody wants to rank it.
Put Important Content in the Initial HTML When Possible
The safest approach is to serve the primary content, headings, links, canonical tags, and metadata in the initial HTML. JavaScript can enhance the experience afterward. This approach is called progressive enhancement, and it remains one of the most reliable patterns for SEO-friendly web development.
For example, an ecommerce product page should include the product name, description, price availability, image references, reviews summary, breadcrumbs, canonical URL, and structured data in a way crawlers can access. JavaScript can power image galleries, variant switching, and personalization, but the core page should not be invisible until the app finishes loading.
Handle Metadata Carefully
Title tags, meta descriptions, canonical tags, robots directives, hreflang annotations, and Open Graph tags should be stable and page-specific. JavaScript frameworks often use head-management libraries to update metadata, but those updates must appear correctly in rendered HTML.
Check for duplicate titles, missing canonicals, conflicting robots tags, and pages where metadata appears only after delayed scripts. A page that says “Loading…” as its title is not sending a strong message, unless the message is “we enjoy preventable ranking problems.”
Use Structured Data That Search Engines Can See
Structured data can help search engines understand products, articles, FAQs, breadcrumbs, organizations, reviews, recipes, events, and other content types. If structured data is injected by JavaScript, test it with search engine tools and inspect the rendered HTML. For important templates, server-rendered JSON-LD is often cleaner and more dependable.
Fix Lazy Loading the Right Way
Lazy loading improves performance by delaying non-critical content, but it can accidentally hide content from search engines if implemented poorly. Google’s lazy-loading guidance warns that deferred content should still become available without requiring user-only interactions such as clicks or swipes.
Use native lazy loading for images where appropriate, include descriptive alt text, provide image dimensions to reduce layout shifts, and make sure content loads when it enters the viewport. Do not hide important text behind “load more” buttons unless the additional content has its own crawlable URL or is not needed for indexing.
Return the Right HTTP Status Codes
JavaScript apps sometimes show a beautiful 404 message while the server returns a 200 status code. That is called a soft 404, and it can confuse search engines. Missing pages should return 404 or 410. Redirected pages should use proper 301 or 302 responses. Server errors should not be disguised as happy little 200 pages.
In single-page applications, configure server-side routing so invalid URLs do not all return the same index file with a successful status. Search engines need the server to tell the truth. Think of status codes as the website’s honesty policy.
Control Duplicates and Canonicals
JavaScript sites often create duplicate URLs through filters, tracking parameters, sorting options, pagination, and faceted navigation. Use canonical tags carefully, but do not use canonicals as a substitute for a clean URL strategy. If multiple URLs display the same content, search engines may choose a different canonical than the one you prefer.
For ecommerce sites, decide which filtered pages deserve indexing. A page for “black running shoes size 10” may have search demand. A page for “black running shoes sorted by newest with session ID 8127” probably deserves a quiet retirement.
JavaScript SEO and Page Speed
JavaScript affects performance because browsers must download, parse, compile, and execute scripts. Large bundles can delay rendering, block interactivity, and hurt Core Web Vitals. Performance is not only a ranking consideration; it is a user experience issue. Nobody wakes up excited to wait for a 2.5 MB JavaScript bundle just to read a paragraph.
Improve speed by splitting code, removing unused JavaScript, compressing files, using HTTP caching, deferring non-critical scripts, preloading essential assets, and limiting third-party tags. Analytics scripts, chat widgets, heatmaps, ad scripts, and personalization tools can pile up quickly. Each one may look small in isolation, but together they become a tiny marching band stomping on your load time.
Testing JavaScript SEO
Compare View Source and Rendered HTML
View Source shows the raw HTML response. Inspect Element shows the browser-rendered DOM after JavaScript has run. Both views matter. If critical content appears only in the rendered DOM, make sure search engines can render it. If it does not appear in either place, congratulations, you found the SEO equivalent of a missing sock.
Use Google Search Console and Bing Webmaster Tools
Google Search Console’s URL Inspection tool can show indexing status, rendered HTML, crawl information, and page resources. Bing Webmaster Tools can help diagnose crawl, indexing, sitemap, and site health issues. Use both platforms because Google and Bing do not always process every technical detail identically.
Crawl With JavaScript Rendering Enabled
Desktop crawlers such as Screaming Frog can render JavaScript and compare crawl results against non-rendered HTML. Screaming Frog notes that crawler rendering is still a simulation of search engine behavior, but it is extremely useful for finding missing content, broken links, duplicate metadata, blocked resources, and rendering differences at scale.
Check Logs and Server Behavior
Server logs show how crawlers actually request your pages and resources. Look for crawl traps, excessive parameter crawling, blocked scripts, repeated errors, and pages that receive crawl activity but never produce indexable content. Log analysis is not glamorous, but neither is flossing, and both prevent expensive problems.
Common JavaScript SEO Mistakes
The first common mistake is assuming that because a page looks good in Chrome, it is automatically search-friendly. Search engines are powerful, but they are not human users. They process pages under constraints, and those constraints matter.
The second mistake is launching a JavaScript framework without SEO requirements in the development brief. SEO should be included during architecture planning, not sprinkled on afterward like parsley on a burned casserole.
The third mistake is ignoring internal links. If your navigation depends entirely on JavaScript click events, crawlers may not discover deep pages efficiently. Use crawlable links for navigation, breadcrumbs, related content, pagination, and category structures.
The fourth mistake is using client-side rendering for every page by default. Some pages need app-like interactivity. Others need fast, stable, indexable HTML. Choose rendering strategies by template and business value, not by trendiness.
The fifth mistake is forgetting Bing. Google usually gets most of the attention, but Bing powers meaningful search experiences across Microsoft products and should be included in technical testing. Bing’s webmaster guidance covers discovery, crawling, indexing, quality, and content accessibility across Bing search experiences.
A Practical JavaScript SEO Checklist
Before Launch
Confirm that every important page has a unique URL, server-rendered or pre-rendered critical content, crawlable internal links, correct metadata, accessible resources, valid canonical tags, useful structured data, proper status codes, XML sitemap inclusion, and mobile-friendly performance.
During QA
Test templates with JavaScript on and off. Crawl the staging site with rendering enabled. Compare raw HTML against rendered HTML. Inspect Search Console and Bing Webmaster Tools after launch. Check whether content, links, schema, canonicals, hreflang, pagination, and robots directives survive rendering.
After Launch
Monitor indexing, rankings, crawl stats, server logs, Core Web Vitals, rendered screenshots, and organic landing pages. Watch for sudden drops after deployments. JavaScript SEO is not a one-time setup; it is an ongoing relationship, like owning a houseplant that occasionally ships a production bug.
Specific Example: An Ecommerce Category Page
Imagine a category page for “women’s waterproof hiking boots.” A risky JavaScript implementation returns an empty app shell, then fetches product data from an API after the browser loads. Product links are clickable cards powered by JavaScript, but they are not anchor tags. The page title is updated after rendering. Filters create endless URL variations. Lazy-loaded products appear only after a user scrolls and clicks “show more.”
A stronger SEO implementation serves the category heading, intro copy, primary product grid, crawlable product links, breadcrumbs, canonical tag, meta title, meta description, and structured data in the initial HTML. JavaScript then enhances filtering, sorting, image galleries, and quick-view features. Important filtered pages get clean URLs only when they have search value. Thin or duplicate combinations are blocked, canonicalized, or kept out of the index strategy.
The difference is not whether the site uses JavaScript. The difference is whether JavaScript supports discoverability or accidentally hides the store from the very crawlers that bring shoppers to the front door.
Conclusion
JavaScript SEO is not about choosing between modern web development and organic search. It is about building modern websites that search engines can reliably crawl, render, index, and rank. JavaScript can create outstanding user experiences, but SEO-critical content should be easy to discover, easy to render, and easy to understand.
The best JavaScript SEO strategy starts early. Choose the right rendering model, use crawlable links, serve important content quickly, manage metadata carefully, avoid blocking resources, test rendered HTML, monitor search tools, and keep performance lean. If your website depends on JavaScript, do not treat SEO as a plugin you install at the end. Treat it as an architectural requirement.
A good JavaScript site should feel fast for users and obvious to crawlers. When both groups can understand the page, everyone wins: developers keep their frameworks, marketers keep their rankings, and search engines do not have to play hide-and-seek with your content.
Experience Notes: What JavaScript SEO Looks Like in the Real World
In real projects, JavaScript SEO problems rarely announce themselves with fireworks. They usually arrive quietly. A new site launches. The design looks polished. The animations glide like butter on a hot skillet. The development team is proud, the marketing team is relieved, and then organic traffic starts acting weird. Some pages index. Some do not. Product pages appear with the wrong titles. Category pages show thin snippets. Google discovers fewer URLs than expected. Bing seems even less enthusiastic. Suddenly everyone is in a meeting called “Indexing Investigation,” which is corporate language for “something is on fire, but politely.”
One of the most common experiences is discovering that the browser and the crawler are effectively seeing different pages. A human visitor lands on a beautiful page after JavaScript runs. But the raw HTML contains almost nothing except a root div, script references, and maybe a loading message. When the site is small, search engines may eventually render enough pages. When the site has thousands or millions of URLs, that extra rendering dependency can become a bottleneck. The fix is not always dramatic. Sometimes moving key content, links, and metadata into server-rendered HTML solves a large part of the problem.
Another familiar situation involves internal linking. Developers often build cards, tabs, menus, and filters with JavaScript click handlers because they work perfectly for users. But if those elements do not include real href links, crawlers may struggle to discover deeper URLs. This is especially painful on ecommerce sites, marketplaces, job boards, travel sites, and directories. A crawler-friendly link structure is like a clean subway map. Without it, search engines are wandering around downtown asking a button for directions.
Metadata issues are also surprisingly common. A React or Vue app may update title tags and canonicals after hydration, but rendering delays or route transitions can create inconsistent signals. One template might ship a default title to hundreds of pages. Another might generate a canonical that points to the wrong version. These are small technical details, but they influence how search engines cluster, index, and display pages. The lesson is simple: test metadata at the template level, not just on one handpicked page that everyone knows is working.
Performance is the other recurring character in the JavaScript SEO story. Heavy scripts can slow down rendering, delay interactivity, and frustrate users. Many teams focus on image compression while ignoring giant JavaScript bundles, third-party tags, and unused code. That is like cleaning the cupholder while the engine is missing. A lean JavaScript strategy often improves both SEO and conversions because users get useful content sooner.
The best JavaScript SEO experiences happen when SEOs and developers work together before launch. The SEO team defines crawlable templates, indexation rules, URL logic, metadata requirements, structured data, and performance goals. The developers choose rendering patterns that support those goals. Quality assurance includes rendered crawls, URL inspection, log checks, and mobile performance testing. Nobody has to become a villain. Nobody has to whisper “technical debt” in a haunted voice. The site simply launches stronger.
The biggest practical lesson is this: JavaScript SEO is not a fight against JavaScript. It is a fight against uncertainty. When you know what the server returns, what the browser renders, what crawlers can access, and what search engines index, the mystery disappears. And when the mystery disappears, rankings have a much better chance to do their job.